Foundation models
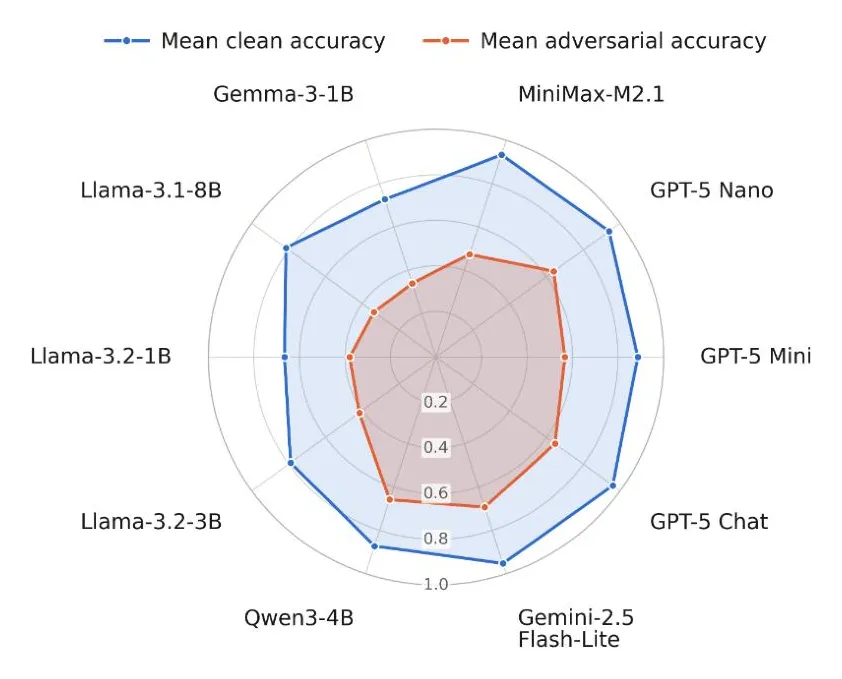
Large pretrained models are now used where a rephrased question or a slightly different camera image can change their answer. We study such failures and how to bound them: adversarial methods that elicit hallucinations with queries that mean the same as the original, validation of vision-language and vision-language-action models over entire continuous regions of image perturbations rather than over samples, what guardrail certificates actually guarantee, and adversarial but intent-preserving user simulation for evaluating multi-turn agents.
Task-specific models, such as image classifiers and object detectors, are under Robust and verifiable machine learning.