Monitoring and explainability
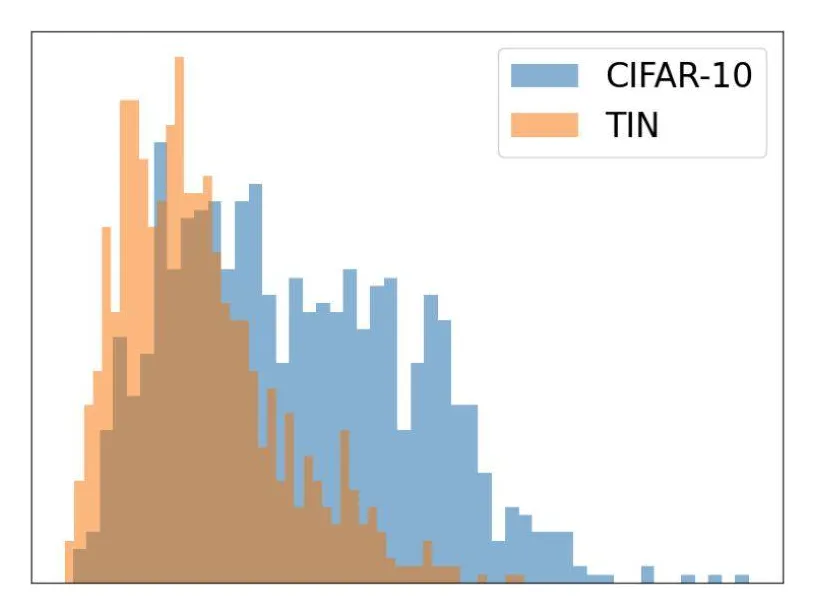
A model can be robust and still be used on inputs it was never meant to handle. We develop methods that flag such inputs at runtime: out-of-distribution detectors that stay reliable under adversarial attack, using the instability of detection scores under smoothing, and detectors based on the distance to the decision boundary, computed with counterfactual explanations that also explain each decision.
We also study explanations for systems in which humans and neural agents interact, and verify formally that these explanations are robust.